As businesses scale, the pipelines that once quietly moved data around start to creak: loads take longer, warehouse bills climb, and “the dashboard is late” becomes a weekly conversation. Modernizing how data gets into and through your warehouse is one of the highest-leverage investments a data team can make.
Starting from ELT
The difference between the two acronyms is where transformation happens: ETL reshapes data before it reaches the warehouse, ELT lands it raw and transforms inside. For teams on a cloud warehouse, landing first is the sensible default — but the choice has more nuance than the usual comparison table admits, and it gets its own treatment here.
The rest of this post assumes the data has landed. What follows is about making what happens next fast and affordable.
Understanding ELT optimization
A working ELT pipeline is not the same as an optimized one. Three pressures show up as data volume grows:
- Bottlenecks — a single slow model or oversized load blocks everything downstream.
- Security and governance — raw data in the warehouse means access control and auditing must be deliberate, not accidental.
- Cost balance — warehouse compute is elastic, which means it will happily burn money on inefficient queries.
Optimization matters because the gap compounds: a pipeline that is 20% inefficient at gigabyte scale is unusable at terabyte scale.
Five strategies for advanced ELT pipelines
1. Incremental loading
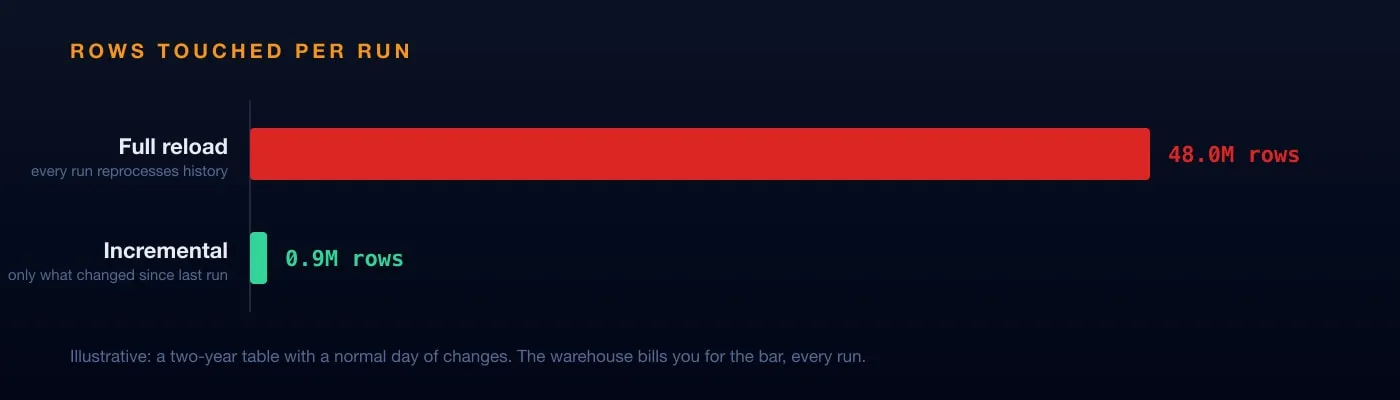
Stop reprocessing history. Load only what changed since the last run — by timestamp, change-data-capture, or high-water marks. This is the single biggest lever for both speed and cost.
2. Parallel processing
Independent models should never wait for each other. Structure your DAG so extraction and transformation fan out across sources and only converge where there are real dependencies.
3. Data caching
Intermediate results that several models share belong in materialized tables, not repeated CTEs. Compute once, read many times.
4. Tackling bottlenecks
Measure before optimizing: find the slowest model, the widest table, the query that scans what it shouldn’t. One targeted fix usually beats ten speculative ones.
5. Filtering unnecessary datasets
Not everything belongs in the pipeline. Trim unused columns, drop dead sources, and archive cold data. Less in, less to transform, less to pay for.
The takeaway
ELT is the right architecture for scale, but architecture alone is not enough — incremental loads, parallelism, caching, and disciplined pruning are what keep it fast and affordable as you grow.
Datablast builds these practices in: incremental loading, dependency-aware orchestration, and quality checks come standard, so your team focuses on the logic instead of the plumbing.
See it on your own data
20 minutes, your questions, a live walkthrough.